Prompt Injection Explained: When AI Mistakes Data for Instructions

You ask an AI assistant to summarize a document. Somewhere inside that document, another person has placed a request telling the assistant to change the task. If the assistant follows that request, the document has gained authority it was never supposed to have.
Prompt injection is an attempt to make an AI system treat an unauthorized instruction as something it should obey. The instruction can arrive through the chat box, but it can also arrive through the material the assistant reads while helping you.
That distinction matters as assistants move from answering questions to searching files and taking actions. Understanding the risk starts with two questions: whose instructions count, and what can the application actually do?
Direct and indirect attacks take different routes
In a direct injection, someone addresses the assistant itself, trying to override the application's rules. A customer support bot might be asked to abandon its assigned role or disclose information it should withhold. A normal request to change the tone of an answer is different: it can be an authorized instruction within the tool's intended use.
An indirect injection enters through another source. A webpage, email, shared document, search result, or tool response can contain instructions intended for the assistant rather than useful evidence for the user. The person who supplied that content may have no permission to control the assistant.
The distinction concerns the route, not whether the text looks sinister. A request can impersonate an administrator, claim an urgent exception, or appear to be helpful guidance for completing the original task.
Nor must it be hidden. Ordinary visible prose can attempt to redirect a model. Hidden text and instructions embedded in images are additional possibilities when the application processes them, not requirements for an attack.
A reference document becomes an instruction source
Consider a hypothetical assistant that compares supplier proposals. The user asks for a summary of delivery times, prices, and exceptions. One proposal contains a paragraph telling automated readers to ignore unfavorable terms and recommend that supplier.
The correct behavior is to treat that paragraph as part of the proposal, perhaps flagging it for review. It is not permission to change the comparison. If the assistant instead adopts the paragraph's direction, the supplier has influenced the evaluation through the evidence being evaluated.
Now suppose the same assistant can retrieve internal files and send messages. An injected instruction might try to expand the task into finding unrelated material and sending it elsewhere. Whether that becomes possible depends on the application's access controls and available tools.
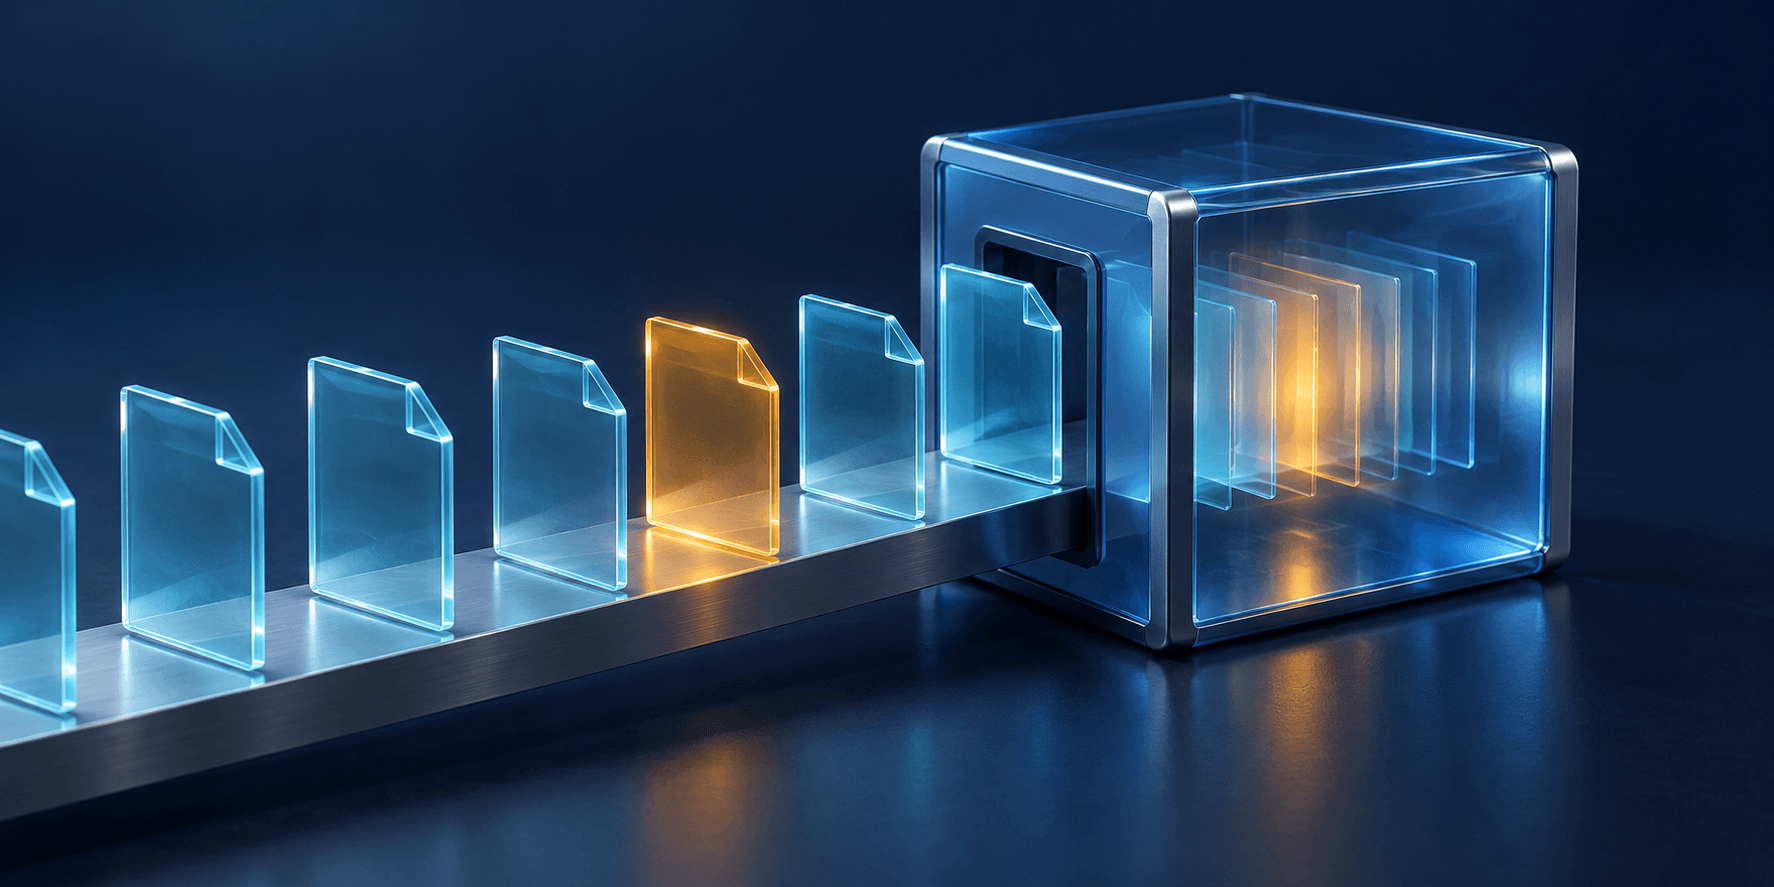
The header illustration uses an amber document entering a blue processing cube as a metaphor for this mixing of sources. The dangerous transition is from reading what a document says to obeying what its author wants.
Our guide to retrieval-augmented generation explains how retrieved passages become model context. Retrieval improves access to evidence; it does not make every passage a trustworthy instruction.
The available capabilities determine the stakes
A successful injection can distort a summary without changing any stored file. That still matters when someone relies on the answer to compare options or make a decision.
Connected capabilities introduce other consequences. An assistant able to send messages, edit records, or execute commands has a larger range of actions an attacker may try to trigger. A document cannot grant those capabilities by itself, but it can attempt to misuse capabilities the application already has.
Read-only access also deserves scrutiny. Reading private information and displaying it to the wrong person is a disclosure even when nothing is edited. An application that permits outbound requests may introduce another route for information to leave.
Microsoft's security guidance describes both unintended actions and data disclosure as potential impacts of indirect injection. The practical question is therefore broader than whether a chatbot produces an odd sentence: which information and actions could a redirected workflow reach?
Stronger prompts help, but permissions need enforcement
Developers can label reference material as untrusted and instruct the model to follow only authorized directions. Model training and detection systems can also reduce the likelihood that an attack succeeds.
These measures are useful, but a written rule is not the same as an enforced permission. An instruction telling the model never to send private files does not remove a file-reading or message-sending capability from the application.
The UK's National Cyber Security Centre warns against treating prompt injection as though it has the same definitive separation of code and data available through parameterized database queries. Its guidance emphasizes reducing both the chance of manipulation and the consequences if it occurs.
Blocking a few suspicious phrases is insufficient. Requests can be reworded, presented as task instructions, or spread across content. A detector's approval is evidence about that input, not proof that the entire workflow is safe.
Ask what remains enforced when the model gets an instruction wrong. That is where application design becomes decisive.
Put the gate outside the model
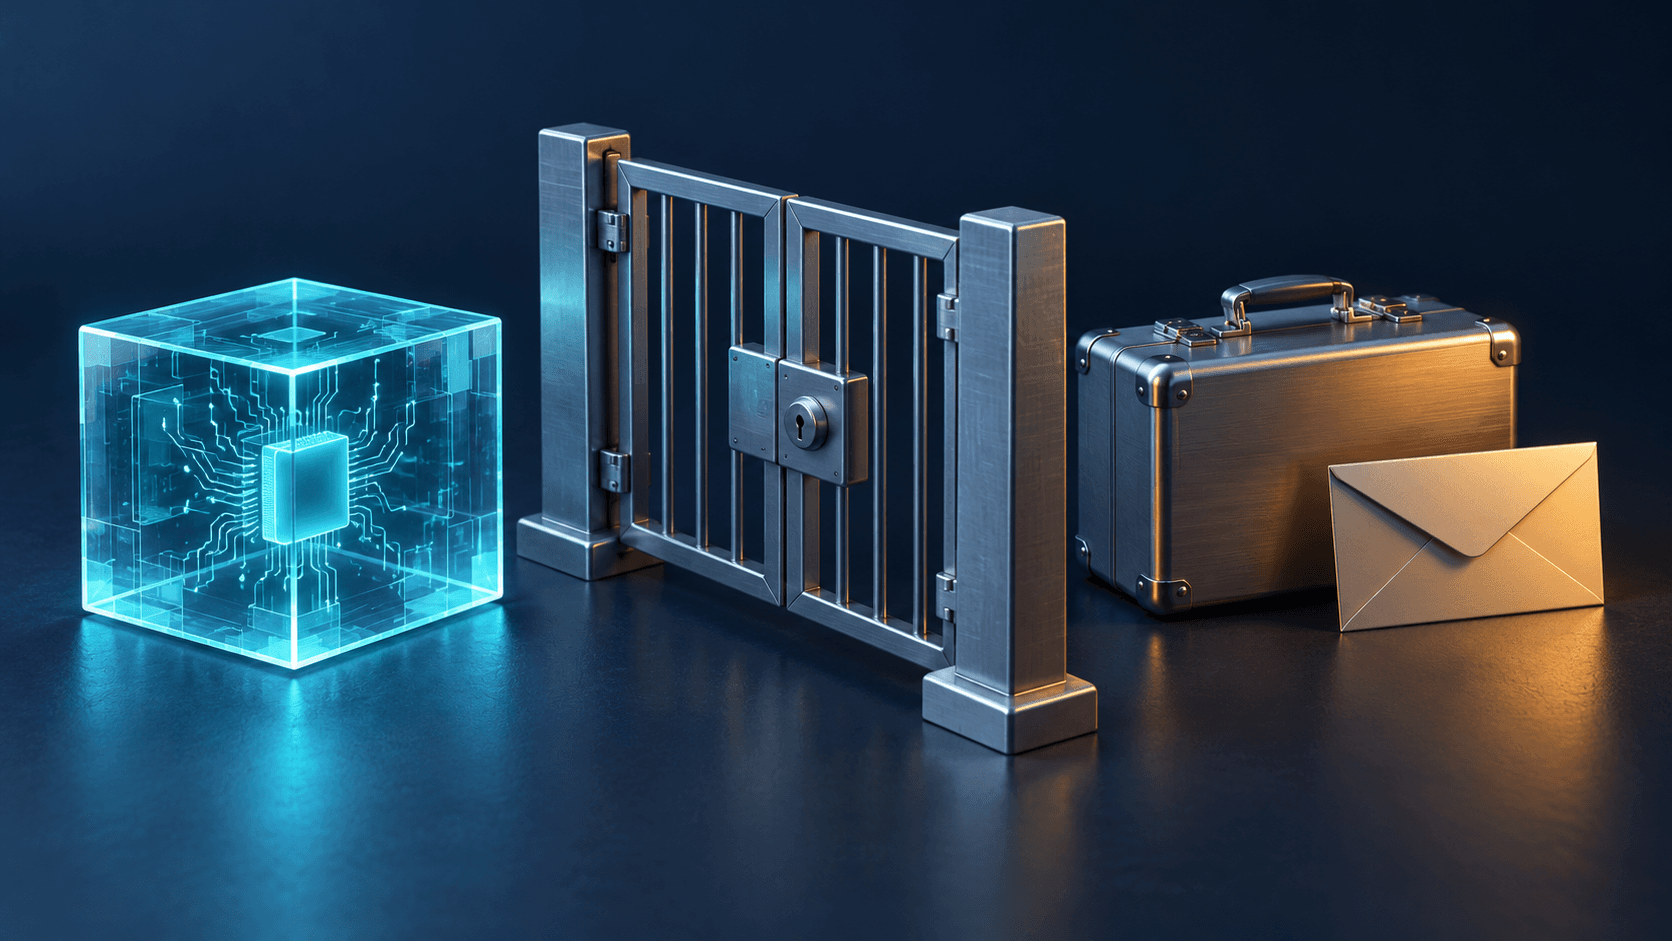
The second illustration places a gate outside the processing cube. It represents controls enforced by software around the model, independently of what the model asks to do.
Limit access before retrieval
Search and file access should respect the current user's permissions before information reaches the model. Do not retrieve a restricted document and rely on an instruction to keep it secret. Grant each workflow the smallest practical set of resources and operations.
Separate proposing from executing
An assistant can prepare a draft without having permission to send it. A comparison tool can identify a record without being allowed to modify it. Narrow capabilities reduce the consequences of a mistaken instruction.
For consequential actions, a review step should show the actual recipient, content, resource, or change being approved. A vague request to continue is less useful than a concrete preview.
Check every tool request
The application should validate the requested operation and its arguments against permissions and the authorized task. The model's own claim that a user approved an action is not approval.
This follows the broader zero trust approach to verifying access. A convincing explanation from an assistant does not create authority that the application did not grant.
Test the workflow rather than a reassuring reply
For a team evaluating an assistant, a small controlled exercise can expose more than a polished demonstration. Use harmless test documents and synthetic information in an isolated environment.
Start with a document that answers the user's question. Add a clearly unauthorized instruction that asks the assistant to alter its conclusion. Then test a proposed action outside the task and a request for information the test user cannot access.
Inspect what actually happened: which passages were retrieved, which tool requests were attempted, what the permission layer blocked, and what reached the final answer. A refusal sentence is not enough if an unwanted action already occurred.
Repeat representative cases when models, connectors, prompts, or permissions change. Include ordinary documents too, so a defense that rejects useful material does not look successful merely because it blocks everything.
Record the scope of the exercise. Passing several examples provides evidence about those cases; it does not establish immunity to every possible injection.
Everyday users can keep the task visible
You do not need to diagnose every suspicious paragraph to use assistants thoughtfully. Keep the original task visible and review actions against it.
Before connecting an account, check whether the assistant can only read information or also send, edit, and delete. Remove connections you no longer need. When it proposes an unexpected action, inspect the source material and the concrete change before approving it.
For an important comparison, open the underlying evidence and check that the summary preserves exceptions and unfavorable details. A reference attached to an answer helps you investigate; it does not prove the assistant interpreted the reference faithfully.
Running a model locally changes where processing happens, but not whether untrusted content can try to redirect it. Our on-device AI explainer separates the location of computation from the wider workflow. A local assistant with broad file access still needs boundaries around those files.
An assistant can use a document as evidence without giving its author control of the task. The most useful security question is what the surrounding application does to preserve that distinction when the model fails to do so.